AI is writing your code. Is your regression testing keeping up?
A green pipeline doesn't mean your code still does what you intended....
AI tools like Claude Code and Playwright have made test generation dramatically faster, but faster test generation isn’t a testing strategy. See why enterprise quality still needs the governance, traceability, and technology coverage no general-purpose coding agent provides.
Key takeaways:
Over the past twelve months, something has shifted in how software teams think about quality. Claude Code, Cursor, and Playwright agents have made it genuinely easy to generate functional tests without deep automation expertise.
The impact is showing up across two very different kinds of teams:
Both paths lead to the same place: tests accumulate without governance, you get coverage without traceability, and there’s automation debt no one owns. But coverage numbers and quality are not the same thing.
What these tools produce is test creation at speed. What they do not produce is a quality engineering function. There is a difference, and it matters enormously at enterprise scale. None of this is an argument against Playwright. Our own architecture absorbs it rather than competing with it — if your developers are already generating Playwright tests, you don’t have to choose. The question is what sits above those tests.
Playwright’s healer agent runs your suite, repairs failing tests automatically, and flags the ones it judges to be genuinely broken. It works — and that’s the problem. Repairs land directly in your test code with no record of which requirement the test was protecting, or whether the fix preserved that intent. When you’re operating at scale with hundreds of test suites changing every sprint, the review burden does not disappear because an AI wrote the original tests. It moves downstream, and out of sight.
Another problem is logic drift. An agent optimizing to make a test pass will sometimes bypass the original intent of the test entirely. It finds a path that achieves the assertion, not the path that validates the business behavior. Your tests stay green, but your product may not be working correctly.
Claude Code and Playwright are impressive tools, but the problem is treating them as a testing strategy rather than a test creation accelerator.
Where AI test generation delivers: The blank page problem. Getting from zero tests to working tests for any given feature has become dramatically easier. This is a genuinely valuable outcome for some teams.
Where it falls short: Governance. Traceability. Cross-team coordination. Regression strategy. Risk-based coverage. Compliance evidence. Test data provisioning and masking. Infrastructure for parallel execution. Cost predictability.
Quality teams have known for years that automation upkeep is a structural drag on engineering capacity. Every sprint that changes the UI cascades into broken locators, stale assertions, and flaky waits.
AI tools accelerate test creation dramatically, but they also amplify the maintenance burden. If you can now generate five times as many tests in the same amount of time, you have also created more maintenance surface area. That debt will accrue silently until it becomes impossible to ignore.
Colas Digital Solutions learned this firsthand. The infrastructure company had tried script-based automation more than once, and each time the maintenance burden eventually killed the initiative. When they finally moved to Tricentis Tosca’s model-based approach, the difference was structural: because tests inherit from a central application model rather than hard-coded scripts, a UI change updates once rather than cascading across every test case that touches that element. They now have 1,400 test scenarios running automatically, with roughly 80% of testing across their target applications fully automated, and the team redirected toward higher-value work.
Maintenance is only one of the gaps coding agents can’t fill. Here are a few more:
Coverage governance
Who ensures that the tests Claude wrote reflect the requirements that matter? Who maps coverage to risk? Who identifies what is missing, not just what is written? A coding agent knows the prompt it was given, not the requirement that prompt came from. With Claude and Playwright, that mapping is yours to build and yours to maintain — usually in a spreadsheet, usually out of date within two sprints.
Enterprise orchestration
How do tests created by developers in their IDEs connect with the test management lifecycle, the performance testing pipeline, and the compliance audit trail? How does the QA function maintain visibility and control when testing is distributed across dozens of engineers using personal AI setups?
Intent preservation
When an application changes, how does the organization know whether a test failure means the feature is broken or the test is stale? That judgment requires context that no self-healing algorithm currently provides reliably.
Test data
This is the gap that stops a generated test from running twice. Playwright and Claude produce test logic; they do not produce the data that logic needs, mask it for GDPR or CCPA, synthesize the edge cases the happy path never touches, or reset state between runs. An agent will write a test that passes once against whatever happened to be in the environment, then fails next sprint because someone consumed the record. At enterprise scale, test data provisioning is not a setup task — it’s a permanent operational function, and with a coding agent it is entirely yours to staff.
Technology coverage
Playwright is a code-first automation framework, and it reaches further than browsers — HTTP APIs, Electron, component tests. What it cannot reach are the systems that carry their own clients and their own semantics. Enterprise business processes don’t stop at the web UI. SAP landscapes, mainframe systems, APIs, data pipelines, and legacy platforms have been running critical business processes for decades. The developer who spins up Playwright tests for the web front-end has not covered the SAP backend that processes the order, the API layer that connects them, or the data warehouse that reports on both. Quality in the enterprise is an end-to-end concern. Playwright was never designed for it, and no amount of AI prompting changes that.
We’ve spent years building the enterprise operating model for quality engineering. That investment positions us to do something no coding agent or open-source framework can: provide the agentic layer that absorbs what Playwright produces, governs what Claude generates, and orchestrates quality across the entire SDLC.
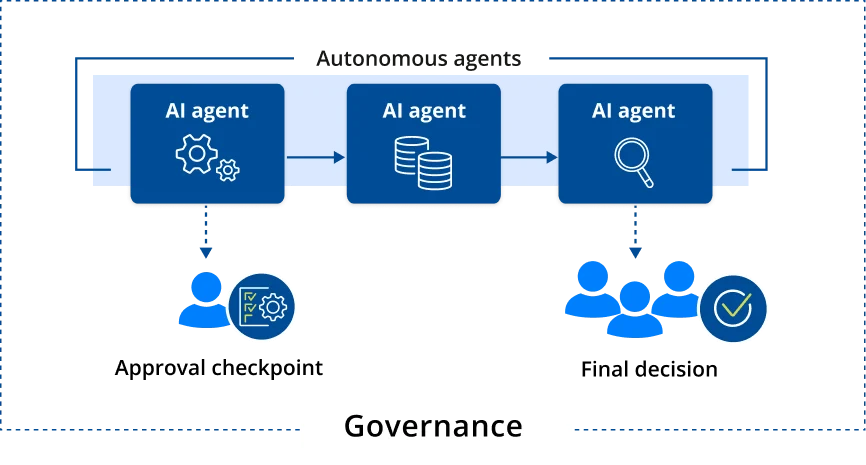
AI Workspace is a cloud-native AI workflow automation hub built specifically for quality engineering teams. Rather than replacing the tools developers are already using, AI Workspace orchestrates autonomous AI agents across the SDLC with governance and human oversight built in.
Teams describe automation goals in natural language. AI Workspace generates the workflow: agents, logic, tool bindings, approval gates. When a requirement changes in Jira, agents propagate that change through test case generation, coverage analysis, and test suite updates in Tricentis qTest, with human-in-the-loop checkpoints for the decisions that matter. There’s no blind automation or silent drift.
Pre-built QE workflow templates deliver immediate value:
Take a product tour of AI Workspace here.
Where Claude Code gives developers a way to generate test scripts in their IDE, Agentic Test Creation gives quality teams an enterprise-grade equivalent: an AI agent that generates context-aware manual and automated test suites from requirements, with full traceability back to the source. The difference is not just the output. It is the governance model around the output.
Learn more about Agentic Test Creation here.
Built in Tricentis Tosca, ATA authors end-to-end tests across 160 enterprise technologies — SAP, Salesforce, Oracle, mainframe, APIs, message queues, and data pipelines among them — from a single model. Tests generated by AI agents, executed through Tosca, managed in qTest, orchestrated by AI Workspace. That’s a quality engineering system, not a collection of scripts.
What that means in practice: a customer places an order in the web storefront, the order posts to SAP, an API syncs fulfillment status, and the finance data warehouse reports on the revenue. Four technologies, one business process. Playwright validates the first step. ATA validates the process — one test, one model, one report, with the assertion on the data warehouse row tied back to the same requirement as the click on the Buy button.
That example is not cherry-picked: 57% of Tosca customers run end-to-end tests that combine web with at least one other technology (Tricentis internal product telemetry.). For nearly six in ten enterprises, a web-only tool covers part of the journey and stops.
That is the structural difference. Governance, traceability, and orchestration are things a determined platform team could argue they will eventually build in CI. Cross-technology, model-based end-to-end coverage is not — and it is the reason a browser automation framework cannot become an enterprise quality strategy no matter how good its agents get.
Learn more about Agentic Test Automation here.
Generated tests are only as reusable as the data behind them. Tosca Test Data Management provisions the data an agent-authored test needs, masks production data so it can be used without violating GDPR or CCPA, generates synthetic records for the edge cases the happy path never reaches, and resets state so a suite that passed yesterday passes again today. This is what turns a test that ran once into a regression asset — and that’s the layer a coding agent leaves on your desk.
Execution at enterprise scale is handled by the Elastic Execution Grid (E2G), the cloud-native execution service of Tosca cloud. Where Playwright requires teams to manage their own infrastructure, parallel execution environments, Docker images, and CI optimization, Tricentis handles all of it. The execution layer scales with demand, not with engineering headcount. That is also what makes cost predictable: you pay for the execution capacity you consume, rather than provisioning and maintaining grid infrastructure sized for peak load all year round.
Learn more about Tosca Test Data Management here.
As promised in the introduction to this piece, this architecture absorbs Playwright rather than competing with it. AI Workspace connects what they’re building with the governance layer your QA team needs. This way, you get the speed without losing traceability.
The deeper differentiator is technology breadth:
The distinction is not how many protocols a framework speaks. It is whether a single test can carry business meaning across systems that do not share a runtime — SAP GUI, a 3270 session, a packaged Oracle back end, a message queue, and the warehouse row where the transaction finally lands. No code-first browser framework does that, however many endpoints it can call. Purpose-built enterprise testing lives in the systems running the actual business processes underneath.
The agentic shift in quality engineering is not about replacing QE teams, but about redirecting QE teams from script maintenance to strategy.
When agents handle test generation, maintenance, and execution monitoring, quality engineers can focus on what they are actually best positioned to do: define what quality means in context, design coverage strategies against real risk, interpret what failures reveal about the product, and govern the AI systems doing the work.
Quality engineers become architects of quality systems. They own the objectives and the governance, and the agents handle the execution.
But that shift requires infrastructure. It requires a platform designed for quality engineering, not a general-purpose AI coding tool repurposed for testing. The governance layer, the traceability, the human-in-the-loop controls, and the enterprise integrations are the foundation.
Most enterprise quality teams are not choosing between two doors. They are already somewhere on a spectrum, and the useful question is where:
Wherever you sit, the cost of moving is lower now than it will be after another two quarters of ungoverned test accumulation.
The question isn’t whether your organization is going to use AI in testing, it’s whether you have a strategy for governing what AI produces.
Learn more about how to embed quality across the SDLC, or talk to our team about AI Workspace.
Learn how to supercharge your quality engineering journey with our advanced testing solutions.
Learn how to supercharge your quality engineering journey with our advanced testing solutions.
VP, Product Management
David Lansberg is the Vice President for Product Management for Tricentis.