
Webinars
3 MCP use cases that demonstrate NeoLoad’s latest agentic capabilities
Join us to see real MCP use cases and a demo of NeoLoad’s latest...
API performance testing measures how APIs handle load, latency, and traffic spikes. Learn the metrics, methods, and tools to get started.
TL;DR
Picture this.
Your app looks fine. Buttons work. Forms submitted. QA signed off last Thursday.
Then Black Friday hits, traffic triples, and checkout stalls for eleven seconds.
Nothing technically broke. Your APIs just got slow.
That gap between “it works” and “it works fast enough, under real load” is where API performance testing lives. And it’s a gap that keeps widening. Modern applications aren’t monoliths anymore. They’re dozens of services talking to each other over APIs, plus a handful of third-party APIs you don’t control.
When one of those calls drags, users feel it immediately.
This guide will walk you through what API performance testing actually measures, how it differs from structural testing, and how to run your first test without guessing. We’ll cover types, metrics, tools, best practices, and how agentic AI is reshaping the whole practice.
Let’s dive in.
API performance testing is the practice of measuring how an API behaves under load, measuring speed, stability, scalability, and resource use rather than correctness. It answers one important question: does this API hold up when thousands of requests arrive at once?
Sometimes performance testing is confused with functional testing. But they ask different questions about their target.
A functional test asks whether `GET /orders/1234` returns the right order.
A performance test asks whether it still returns that order in 200 milliseconds when 5,000 users hit it simultaneously.
API performance testing sits at the protocol layer. You’re sending real HTTP, REST, SOAP, GraphQL, or gRPC requests directly to endpoints. No browser, no rendered UI, no waiting for JavaScript. That makes it fast, cheap, and easy to run early, long before a front end exists.
Furthermore, API performance testing validates non-functional requirements: response time, throughput, error rate, and resource consumption under concurrent load.
As stated before, people conflate these constantly, so let’s separate them more clearly.
Functional API testing verifies that an API returns correct responses, status codes, and data structures for a given input. It’s essentially a pass/fail check on behavior, and one slice of the broader API testing discipline.
Performance testing, on the other hand, assumes the API already works. It then applies pressure and watches what bends.
API performance testing validates non-functional requirements: response time, throughput, error rate, and resource consumption under concurrent load.
| Functional API testing | API performance testing | |
| Core question | Does it return the right answer? | Does it stay fast and stable under load? |
| Users simulated | One | Hundreds to millions |
| Primary output | Pass or fail | Response times, throughput, error rates |
| Typical failure | Wrong payload, wrong status code | Timeouts, 503s, memory leaks, saturation |
| Runs in | Seconds | Minutes to hours (or days for soak tests) |
Here’s the practical link between them. Your functional test suite already documents every endpoint, parameter, and valid payload. That’s most of the work.
Tools like Tricentis NeoLoad can convert existing Tricentis Tosca functional tests into performance test scripts so you’re not rebuilding assets from scratch.
APIs carry the business logic now. A slow API isn’t a backend inconvenience; it’s a slow product.
User tolerance for delay hasn’t moved in decades. Jakob Nielsen’s research at Nielsen Norman Group identified one second as “the limit for the user’s flow of thought to stay uninterrupted.” Past that, people notice. After ten seconds, they leave.
Your API budget is a slice of that one second. A single page might trigger eight API calls. If each takes 300ms, you’ve already blown past the threshold.
The stakes climb higher in a few specific situations:
There’s also a cost argument. Finding a bottleneck in staging costs an afternoon. Finding it in production costs an incident, a rollback, and a week of engineering time.
Performance testing doesn’t just tell you something is slow. Paired with observability data, it tells you which of these is the culprit.
Before you test, it helps to know what usually goes wrong. Most API slowdowns trace back to a short list:
Performance testing doesn’t just tell you something is slow. Paired with observability data, it tells you which of these is the culprit.
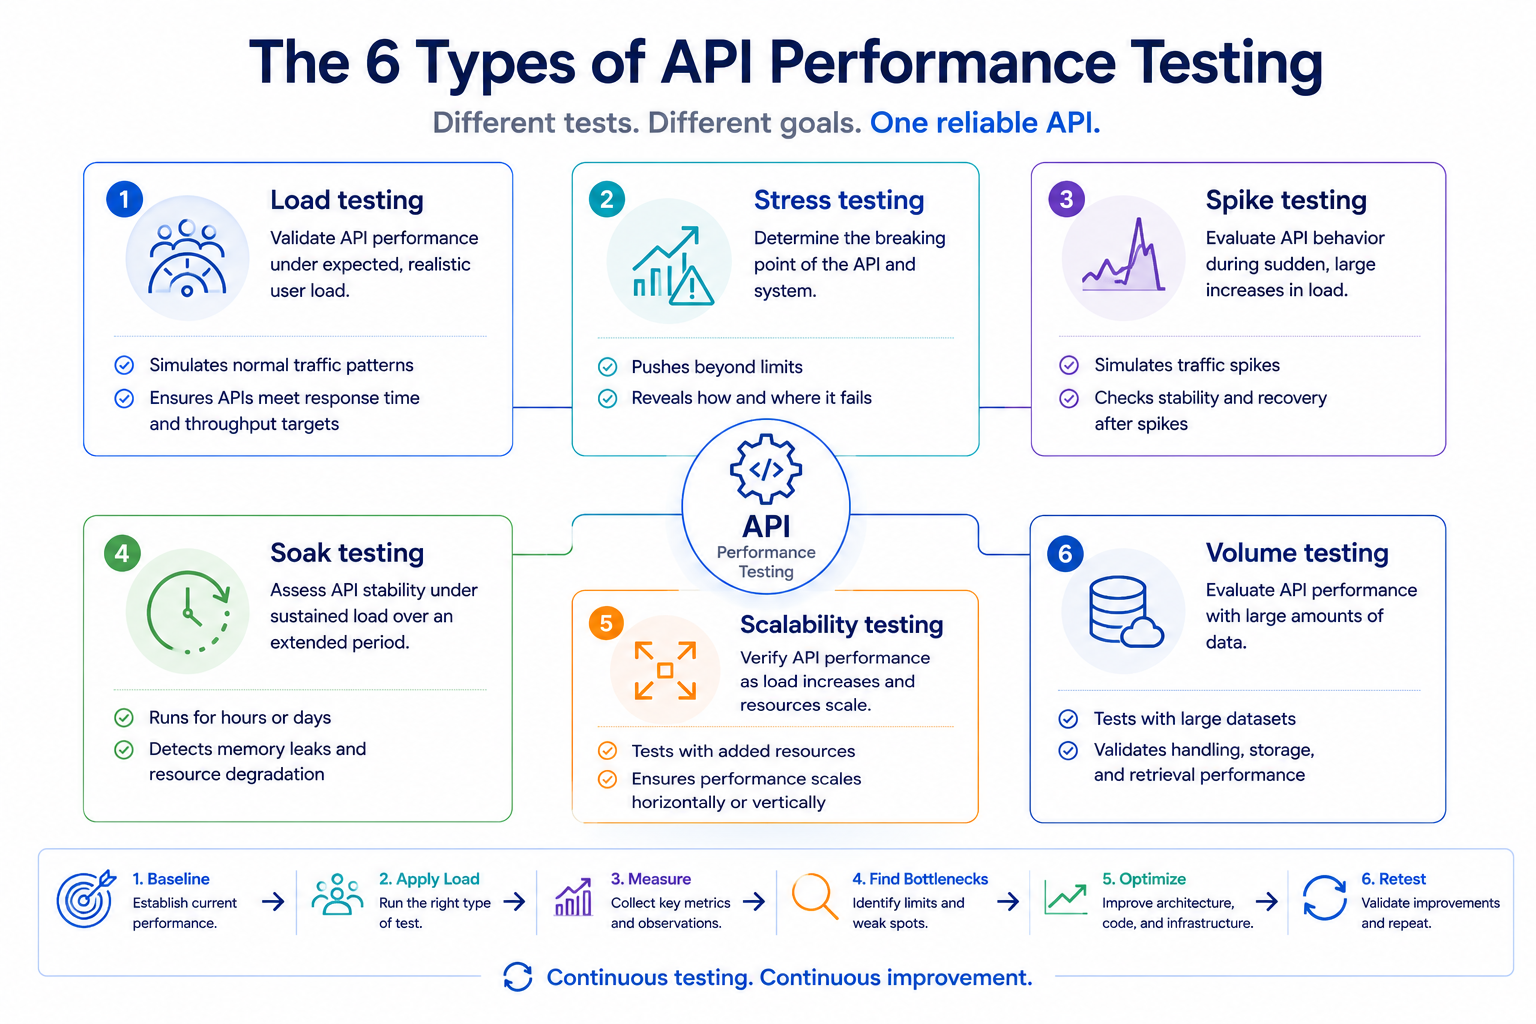
Different questions need different test shapes. Here are the six you’ll actually use.
Load testing measures API behavior under an expected, realistic volume of concurrent requests. This is your baseline check. Simulate a normal Tuesday, or a normal peak hour, and confirm response times stay within your targets.
Stress testing pushes an API past expected capacity to find its breaking point. You ramp load until something fails. The goal isn’t to pass. It’s to learn where the ceiling sits and how the system fails when it gets there. Graceful degradation beats a hard crash.
Spike testing applies a sudden, extreme jump in traffic to see how quickly an API recovers. Think of a product launch or a news mention. Load goes from 100 to 10,000 users in thirty seconds. Does autoscaling keep up? Does the connection pool survive?
Soak testing runs a moderate, sustained load over many hours to expose slow-building problems. This is how you catch memory leaks, log files filling disks, and connection handles that never get released. A four-hour soak reveals issues an eight-minute load test never will.
Scalability testing measures how performance changes as you add users, data, or infrastructure. You’re looking for the shape of the curve. Does doubling your servers actually double throughput, or does a shared database cap you at 1.4x?
Volume testing evaluates API performance against large data sets rather than large user counts. A search endpoint that flies over 10,000 records may crawl over 10 million.
Start with load testing. Add stress and soak once you have a baseline. Reach for spike and volume testing when your traffic pattern or data growth justifies it.
The four golden signals of monitoring are latency, traffic, errors, and saturation.
You can drown in metrics. Google’s site reliability engineering team offers a useful filter: “The four golden signals of monitoring are latency, traffic, errors, and saturation.” That framework maps cleanly onto API performance testing.
Here’s what to instrument, and why.
| Metric | What it tells you | Watch out for |
| Response time (percentiles) | End-to-end time per request | Averages hide pain—track p90, p95, p99 |
| Latency | Time taken to service a request, including network and processing delays | Distinguishes network issues from app issues |
| Throughput | Requests or transactions per second | Falling throughput under rising load signals saturation |
| Error rate | Percentage of failed requests | A 2% error rate at peak is a real outage |
| Concurrent users / virtual users | Simultaneous load applied | Must reflect real usage, not a round number |
| Time to first byte (TTFB) | Server responsiveness | Rising TTFB often points to queuing |
| CPU, memory, thread pools | Resource saturation | The leading indicator before errors appear |
| Database query time | Backend bottlenecks | Usually the top cause of slow endpoints |
One rule deserves its own line: average response time is the least useful performance metric you can report. If your average is 200ms but your p99 is 8 seconds, one in every hundred users is having a terrible experience. That’s thousands of people a day at scale.
Track percentiles. Report percentiles. Set SLAs on percentiles.
Here’s a workflow you can run this week.
Write down concrete targets before you test—for example, “P95 under 500ms at 2,000 concurrent users, error rate below 0.5%.” Vague goals produce vague results.
You don’t need to test all 300 APIs. Pick the ones tied to revenue, the ones with the heaviest traffic, and the ones that recently changed. Ten endpoints usually cover 80% of the risk.
Real users don’t hammer one endpoint in a loop. They browse, search, add to cart, then check out. Model the actual mix and the actual think times between calls.
Use production-like data volumes. A search API tested against 500 rows tells you nothing. Sanitize sensitive data, and parameterize inputs so you’re not caching the same response repeatedly.
Import an OpenAPI or Swagger definition to generate scenarios automatically instead of hand-writing requests. NeoLoad supports Swagger/OpenAPI imports, plus codeless design and YAML-based test-as-code for teams that prefer working in an IDE.
Run a light load first and record the numbers. Every future test compares against this. Without a baseline, you can’t tell improvement from noise.
Run the test while watching application and infrastructure metrics side by side.
Run the test while watching application and infrastructure metrics side by side. NeoLoad integrates with APM tools like Dynatrace, AppDynamics, and New Relic so you can correlate a response time spike with the exact backend resource that caused it.
Look for the inflection point where response times climb while throughput flattens. That’s your saturation point. Then trace it to a specific service, query, or resource.
Change one thing at a time. Otherwise you won’t know what worked.
Add a performance gate to your pipeline with defined SLAs. NeoLoad provides CI/CD integrations and a CLI so tests run automatically on every build, failing the pipelines when thresholds break.
That last step is what turns performance testing from an event into a practice.
Consider this case study.
SAP is what Dell’s Management Information Systems Director Ranbir Singh calls the “backbone of the business.” Two thousand sales representatives use it daily, and it handles 35,000 orders per quarter.
Dell already tested most applications with Tricentis NeoLoad, but ran a separate legacy tool for its critical SAP workloads. Two platforms meant two skill sets, two maintenance burdens, and inconsistent results across the estate. An S/4HANA migration was also approaching.
Dell brought SAP GUI testing into NeoLoad alongside its Java-based SAP Hybris application, consolidating on a single platform. The performance engineering team certifies every release and can block any build that misses its performance targets.
That gate runs on ten performance tests per release, roughly 120 tests executions per year. NeoLoad’s integration with Dynatrace lets the team analyze the application under test in far more depth than reporting alone.
A straightforward project now takes upwards of 40% less time to design and script. Test maintenance saves 30% in time and effort compared with the legacy tool.
Analysis improved qualitatively too: Dell can now pinpoint bottlenecks at the transaction level, where the legacy tool only showed user-level visibility.
Scripting, execution, and analysis all happen in one interface. As Singh put it, the team is “much more efficient from an issue identification and reconciliation perspective.”
You can read more about this case study here.
Look for automatic script update capabilities, or you’ll spend more time fixing tests than running them.
Tools generally fall into four categories.
| Tool type | Best for | Trade-off |
| Open-source frameworks | Small teams, script-comfortable engineers, tight budgets | You own maintenance, scaling, and reporting |
| Cloud/SaaS load generators | Burst capacity without managing infrastructure | Limited protocol coverage and enterprise app support |
| Enterprise platforms | Complex environments, SAP/ERP, governance, CI/CD at scale | Requires investment and rollout planning |
| In-house scripts | Very narrow, one-off checks | Fragile, undocumented, and rarely maintained |
Our full breakdown on how to choose a load testing tool goes deeper, but when evaluating options, weigh these criteria:
Don’t over-index on price per virtual user. The real cost is engineering hours spent maintaining scripts.
Agentic performance testing uses autonomous AI agents to design, execute, analyze, and adapt performance tests based on real system behavior.
You already know what agentic AI is: systems that plan, act, evaluate results, and adjust without step-by-step instructions. And you already know API performance testing. The interesting part is the intersection.
Agentic performance testing uses autonomous AI agents to design, execute, analyze, and adapt performance tests based on real system behavior. The agent doesn’t just suggest; it acts.
Here’s where that changes daily work:
Instead of manually scripting 40 endpoints, an agent reads your API definition and generates realistic scenarios, including correlation and parameterization.
Agents can analyze production patterns and propose a load profile that matches actual user behavior, rather than a guessed 80/20 split.
This is the biggest immediate win. Sifting through a three-hour test run to find the moment a thread pool saturated used to take an engineer half a day. Tricentis reports that agentic analysis reduces investigation and reporting time by up to 90-95%.
An agent cross-references response time spikes with CPU, memory, and query metrics, then reports the probable cause instead of the symptom.
NeoLoad’s embedded AI Chat drives agentic and Model Context Protocol (MCP) workflows through plain language, so a developer can ask about a regression without learning the full UI.
Agents compare each run against historical baselines and flag meaningful deviations, filtering out normal variance.
API performance testing isn’t optional infrastructure work. It’s how you find out whether your product survives its own success.
Start small. Pick five critical endpoints. Define a p95 target. Run a load test. Establish a baseline. Then automate it into your pipeline and let it run forever.
Tricentis NeoLoad handles protocol-based testing for APIs, microservices, and backend services, plus browser-based testing with RealBrowser, all in one interface.
It supports codeless and as-code design, OpenAPI import, CI/CD and APM integrations, and agentic AI workflows that turn raw test data into decisions.
Explore Tricentis NeoLoad or request a demo or free trial to run your first API performance test.
Learn more about continuous performance testing and how to deliver performance at scale.
Learn more about continuous performance testing and how to deliver performance at scale.

Performance testing for an API measures how that API responds under concurrent load. It captures response time, throughput, error rate, and resource consumption while simulating many simultaneous users.
API testing validates the application programming interfaces that let software components communicate. It covers functional correctness, security, reliability, and performance.
Tests are sent directly to endpoints at the protocol layer, without a user interface, which makes them faster and more stable than UI tests.
It depends on the operation, but general benchmarks are useful. Anything less than 100ms feels instantaneous. Under 300ms is excellent for most user-facing endpoints.
Under 1 second keeps users in flow. Anything above 2 seconds needs justification, and complex reporting or batch endpoints should show progress feedback.
Run a lightweight performance check on every build in CI/CD, using SLA thresholds to gate the pipeline. Conduct fuller load and stress tests before each major release. Run soak tests at least monthly and before high-traffic events.