
Reports & White Papers
AI-powered test automation for the next generation of applications
Tricentis Tosca’s Vision AI delivers faster, more resilient test...
Learn what model-based testing is, how it works, its benefits, challenges, and best practices for improving software quality and test automation.
TL;DR
Modern software development moves fast, but traditional test automation hasn’t kept up. Script-based testing forces QA teams into a cycle of writing, breaking, and fixing scripts and harnesses every time an element ID shifts or a UI updates.
Model-based testing (MBT) addresses this ongoing process by decoupling an application’s implementation from its business logic. So, instead of relying on brittle, hand-coded scripts, MBT uses abstract models to generate, execute, and update resilient test suites.
In this comprehensive guide, we’ll break down how MBT works, explore the most common models used in production, and examine how enterprise teams scale it to reduce overhead and accelerate release cycles.
The obvious answer to the question “What is model-based testing?” would be “testing based on models.” So, let’s define what we mean by “model” when we’re discussing software and software design.
Developers, testers, and architects use models as a tool for reasoning about systems that span thousands or even millions of lines of code.
A model is an abstract, structured representation of an application’s or system’s logic, behavior, and interfaces. Developers, testers, and architects use models as a tool for reasoning about systems that span thousands or even millions of lines of code.
These models can take several forms, depending on what your development and testing goals are. For example, a graphic user interface (GUI) designer might create a wireframe model of user interface (UI) elements.
A systems architect could use a blueprint representing application programming interface (API) endpoints, and a developer could make a behavior model like a truth table part of their toolkit.
A model often serves as a single source of truth for an application or system, which is useful when it’s time to design tests.
Model-based testing (MBT) is a software testing methodology that derives test cases, data, and schemes from one or more models that represent the intended behavior and architecture of the application under test.
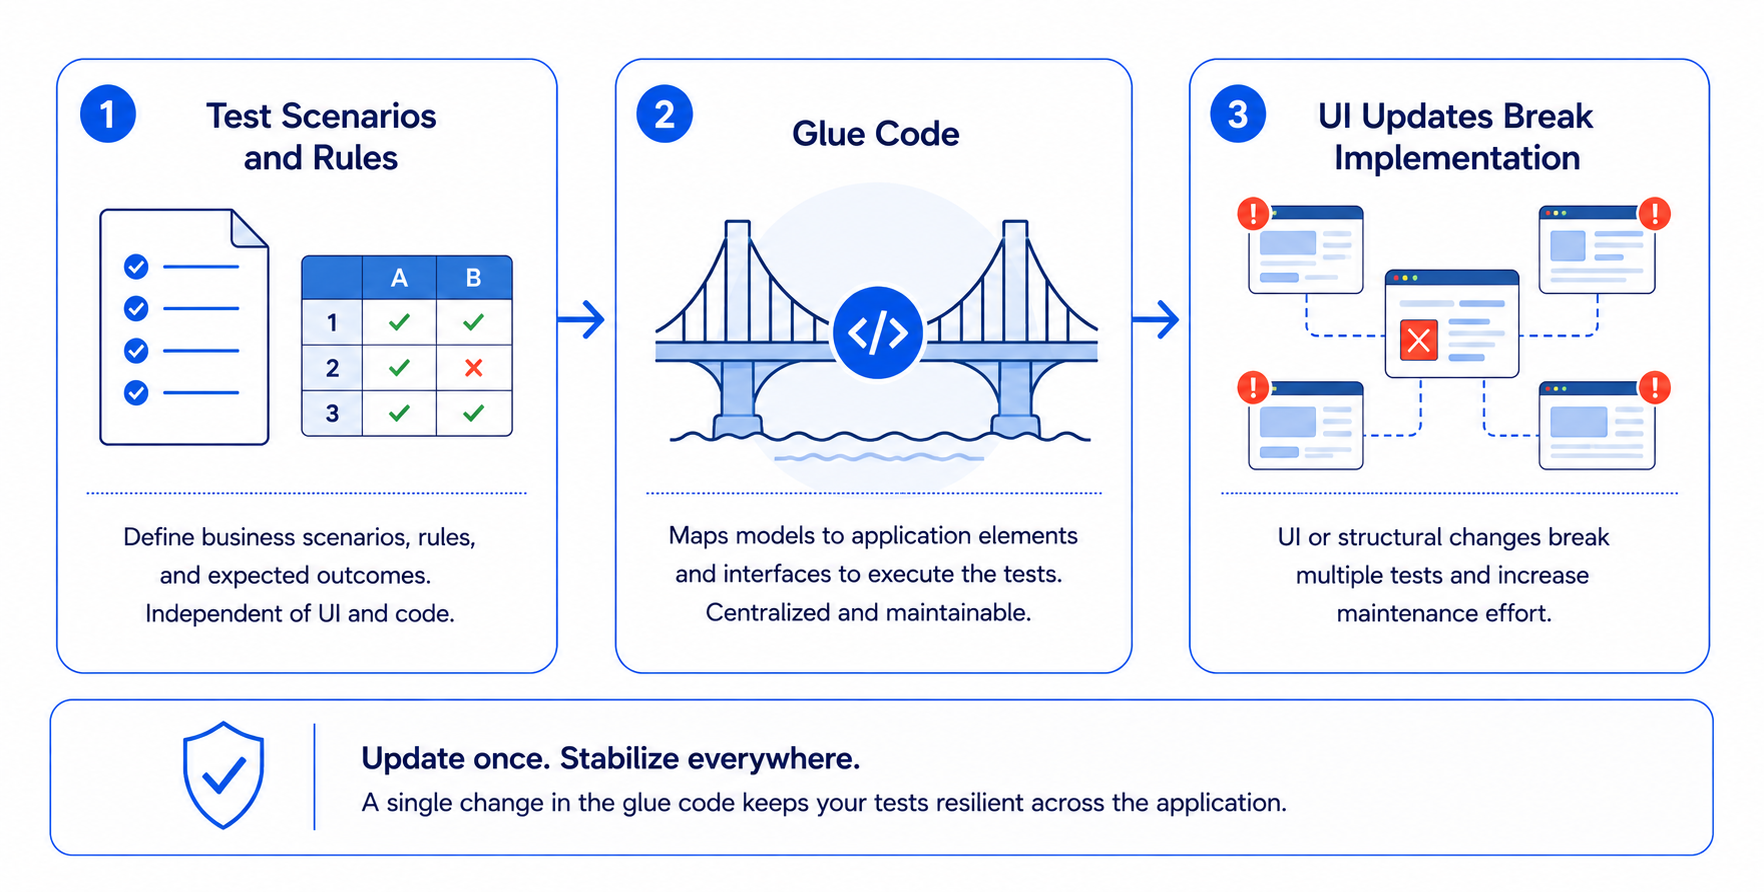
In script-based test automation, QA engineers create code that interacts directly with specific application elements and interfaces.
These scripts tend to hardcode their technical implementation alongside their test logic, so even minor changes render the tests obsolete. This approach leads to high maintenance overhead and slows the development pipeline.
By decoupling test logic from application implementation, MBT makes your tests more robust.
Traditional test implementations have “glue code” that makes tests brittle. So, a change to a user interface almost always leads to test failures.
Model-based tests, on the other hand, are based on abstractions, so they handle updates more readily:
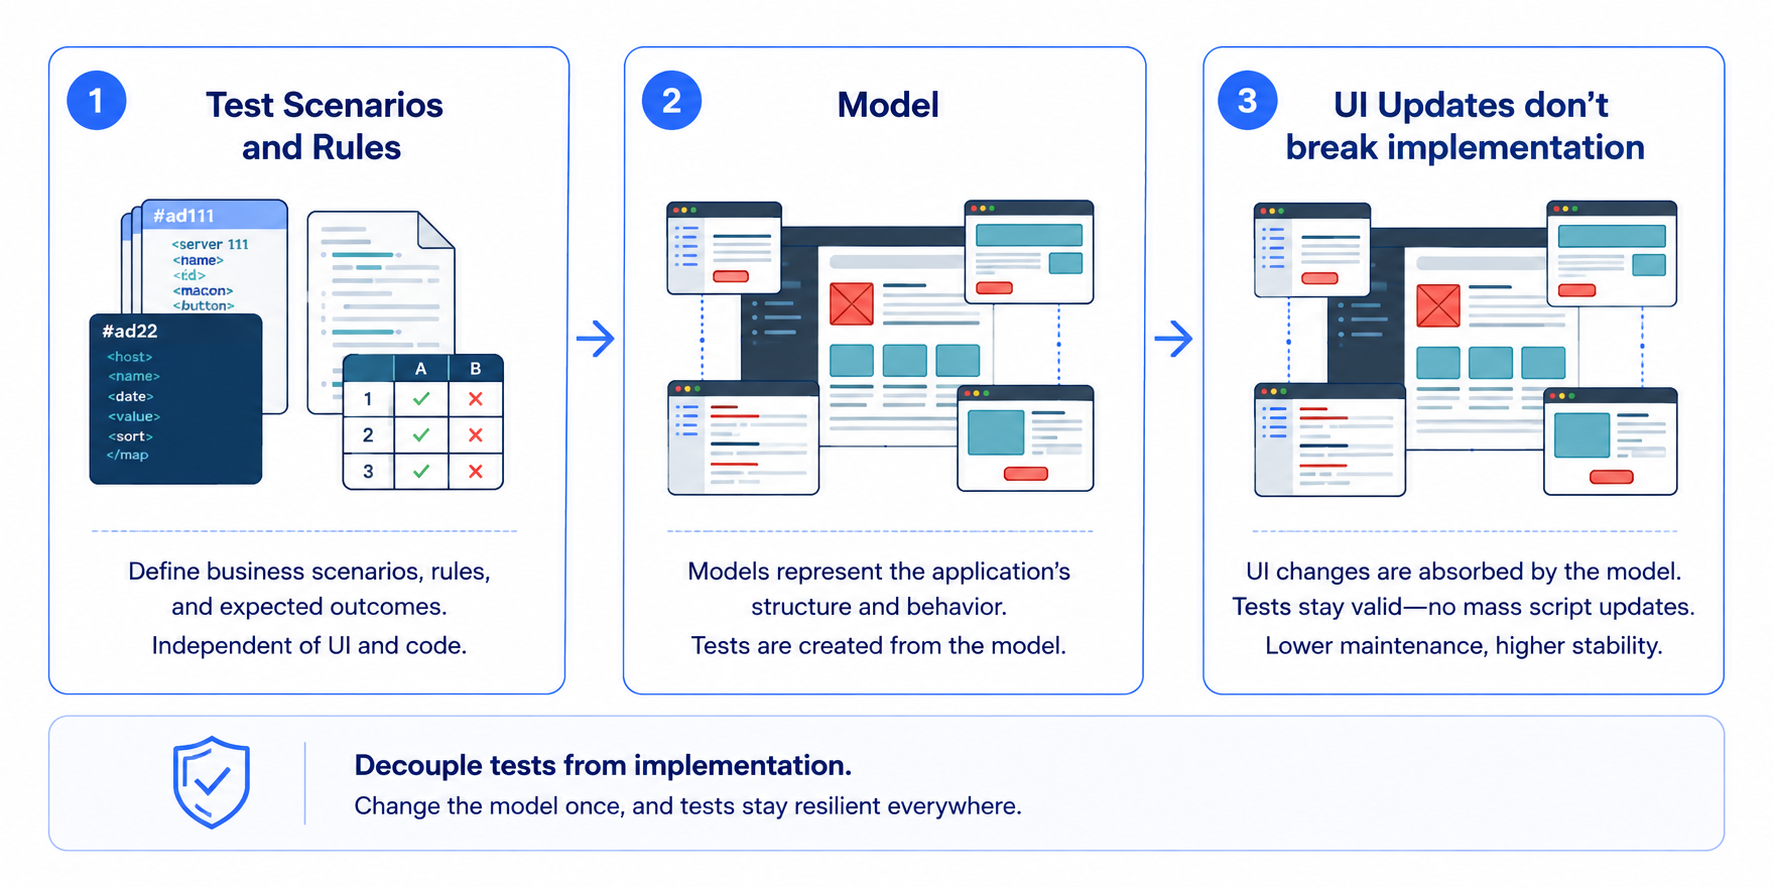
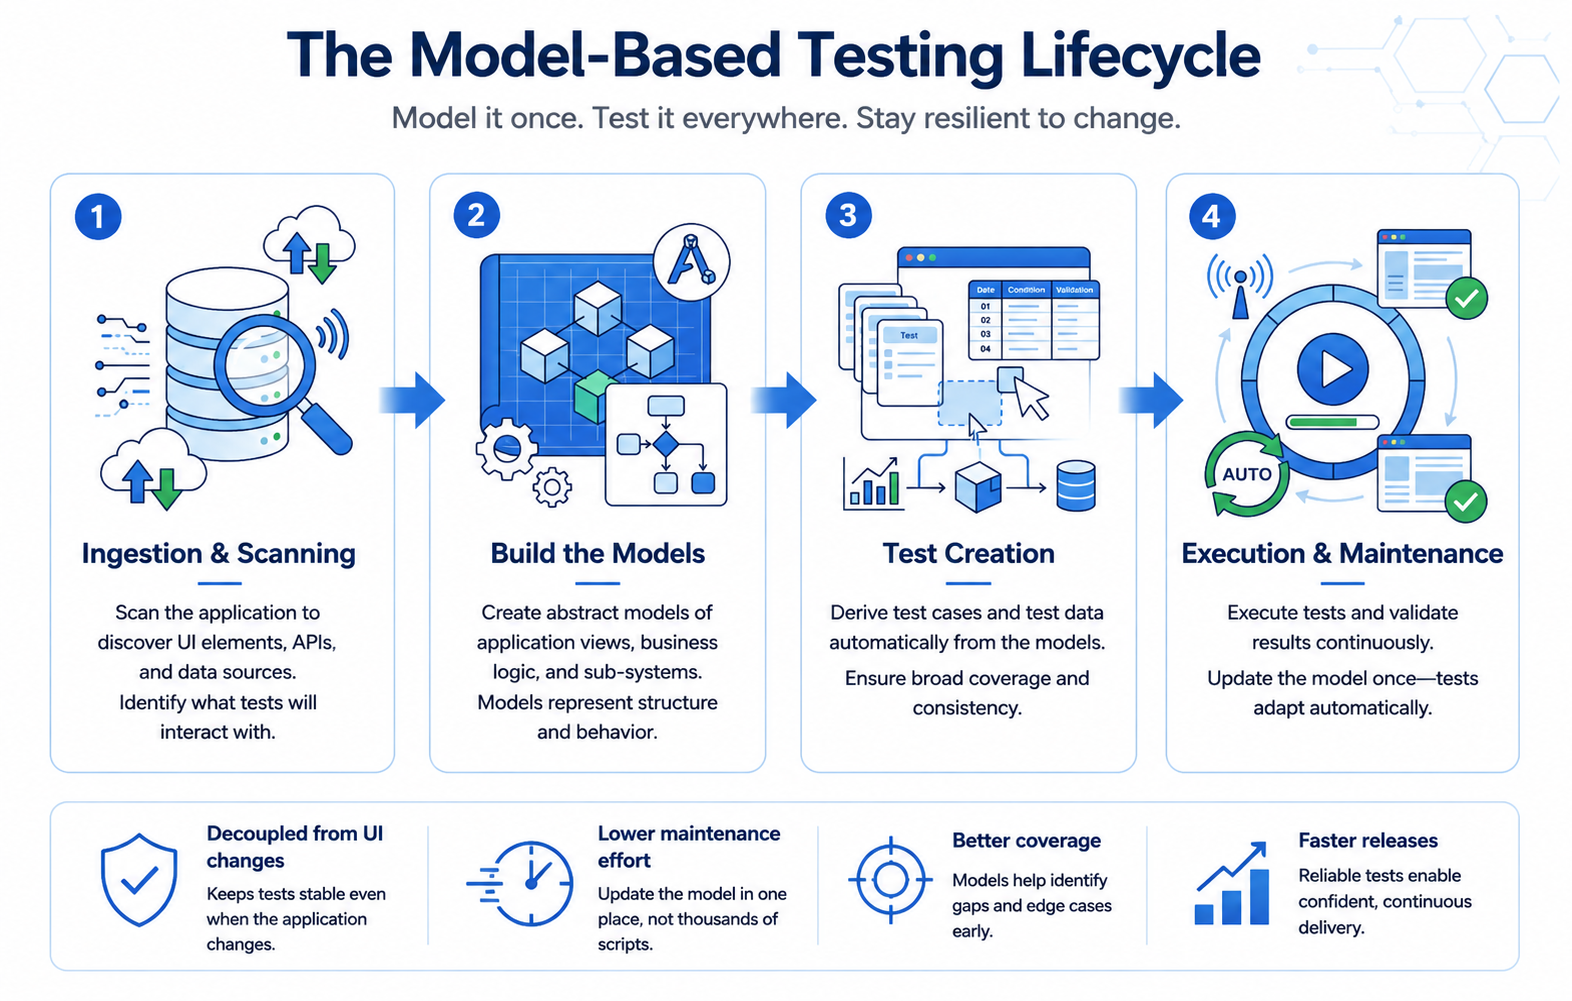
For some, creating tests that withstand nontrivial application changes sounds like magic, but that’s not the case at all. Model-based testing, when implemented with the right tools, is a straightforward process with a clear, four-stage lifecycle.
“Model-based testing builds on previous generations of testing tools. Like the action-word and keyword-based approaches to testing, model-based testing relies on abstraction, and like the automated test script approach, it produces executable scripts.” — Mark Utting and Bruno Legeard, Practical Model-Based Testing: A Tools-Approach (2007)
The first step in model-based testing is identifying the components that make up the models. This is most often done by scanning the code with an automated tool that identifies how the tests will drive the application.
The tool inspects the UI, Document Object Model (DOM), API, or database layers to extract controls and interfaces. These elements are where tests interact with the application.
Instead of relying on library calls or other methodologies that rely on the application’s implementation, these tests live outside the underlying code. So when the application changes, only a new scan is required, as opposed to modifying or creating a test harness.
Now it’s time to take that list of UI elements and API calls into a blueprint of how the application works. This blueprint often takes the form of visual elements that a tester can reason about and manipulate in a GUI.
Why is this step necessary? We’ve already assembled a comprehensive list of interface elements, so we know how to drive the application. Why not get right to work creating tests?
Without models, the elements and the features they test are scattered across scripts. They’re isolated from your application’s code, which goes a long way towards making your tests easier to maintain.
But they’d still be an unstructured jumble of code with no unifying model. So, the tool consolidates the elements into representations of views and operations, such as “Login Screen,” “Checkout,” or “Process Payment.”
This step goes further in decoupling your business logic from your application’s implementation. The next step demonstrates how you do this.
Now, we have visual models that QA engineers, developers, and domain experts can manipulate to create tests without touching a line of code. Testers manipulate the models, and the platform creates the corresponding tests.
These tests can take the form of entire user journeys instead of simply testing a single element or application screen. So, a tester can create a test that represents a shopping experience:
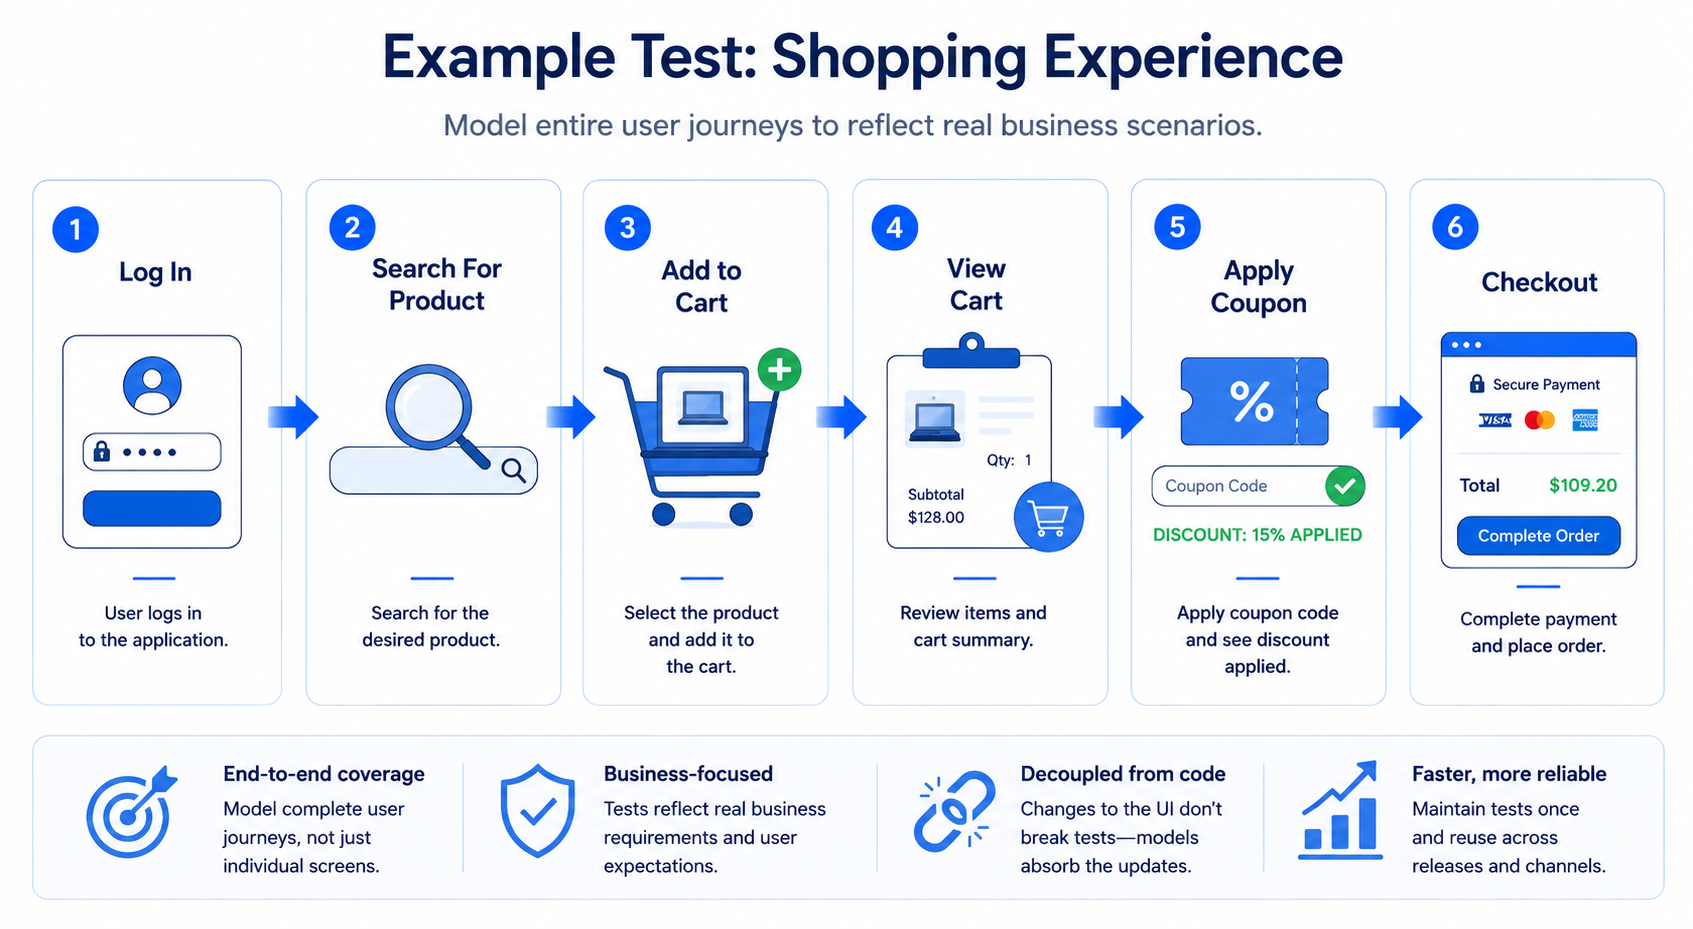
This equips testers with clear test cases that reflect business requirements that are completely decoupled from application code.
Step three left us with comprehensive tests that you can run in CI/CD pipelines and integration environments. So, these tests verify your end-to-end business logic at regular intervals.
When your application changes, you rescan the affected components or, if the changes are broad enough in scope, update the core models. But this is a process you perform once for each change, and there’s still no need to manually alter test code.
The models in MBT aren’t one-size-fits-all, and they’re not made up on the spot.
The models in MBT aren’t one-size-fits-all, and they’re not made up on the spot. Your testing goals and application architecture require different modeling techniques. Depending on whether you’re trying to verify your business logic or user interface controls, you’ll rely on specific behavioral or structural approaches.
Here are the most common models used in MBT:
A finite state machine (FSM) is a model for representing a system that occupies one of a finite number of states at any time. The system transitions from one state to another when triggered by an event, which may be user input or a message from another system.
In model-based testing, finite state machines provide you with a clean way to map out event-driven business logic. Rather than manually mapping out individual code paths, an MBT tool uses an FSM to analyze all valid (and invalid) state transitions and generates test paths that cover them.
An FSM comprises these components:
The specific conditions or modes the application can reside in. For example, an e-commerce app might have “Logged Out,” “Empty Cart,” “Active Cart,” and “Payment Pending.”
Triggers supplied by a user or external system. The same sample application could use “Login,” “Add Item,” “Inventory Empty,” “Check Out,” and “Enter Payment.”
The rules that govern how an event moves the model from one state to another. An e-commerce rule would say that the application cannot transition to “Check Out” with an empty shopping cart.
The response the system generates during or after a state transition—sjo, error messages, receipts, etc.
Let’s dive a little deeper into our e-commerce example by seeing how an MBT platform might map an FSM for an e-commerce website into a set of simple tests.
| Current state | Event | Target state | System output | Scenario type |
| Empty cart | Add item | Active cart | Increment cart counter | Positive path |
| Active cart | Checkout | Pending payment | Order summary displayed | Positive path |
| Pending payment | Payment succeeded | Processing | Send confirmation email; send a shipping message to the warehouse | Positive path |
| Pending payment | Payment failed | Payment failed | Display retry button | Error path |
| Processing | Cancel order | Cancelled | Issue refund message to processor | Positive path |
| Processing | Item shipped | Completed | Send tracking email | Positive path |
| Completed | Cancel order | Invalid transition | Send rejection message | Error path |
Using finite state machines to generate tests offers QA engineers and product designers several benefits. Here are some of the primary ones:
FSMs force you to define what happens during invalid transitions, like trying to edit an address after an item ships.
MBT tools use graph traversal algorithms in an FSM to automatically generate the shortest path of test cases to achieve complete state and transitions.
If you need to add a new state, such as “Awaiting Warehouse Pick,” you can add the new node and associated transitions and allow the MBT to create the new tests.
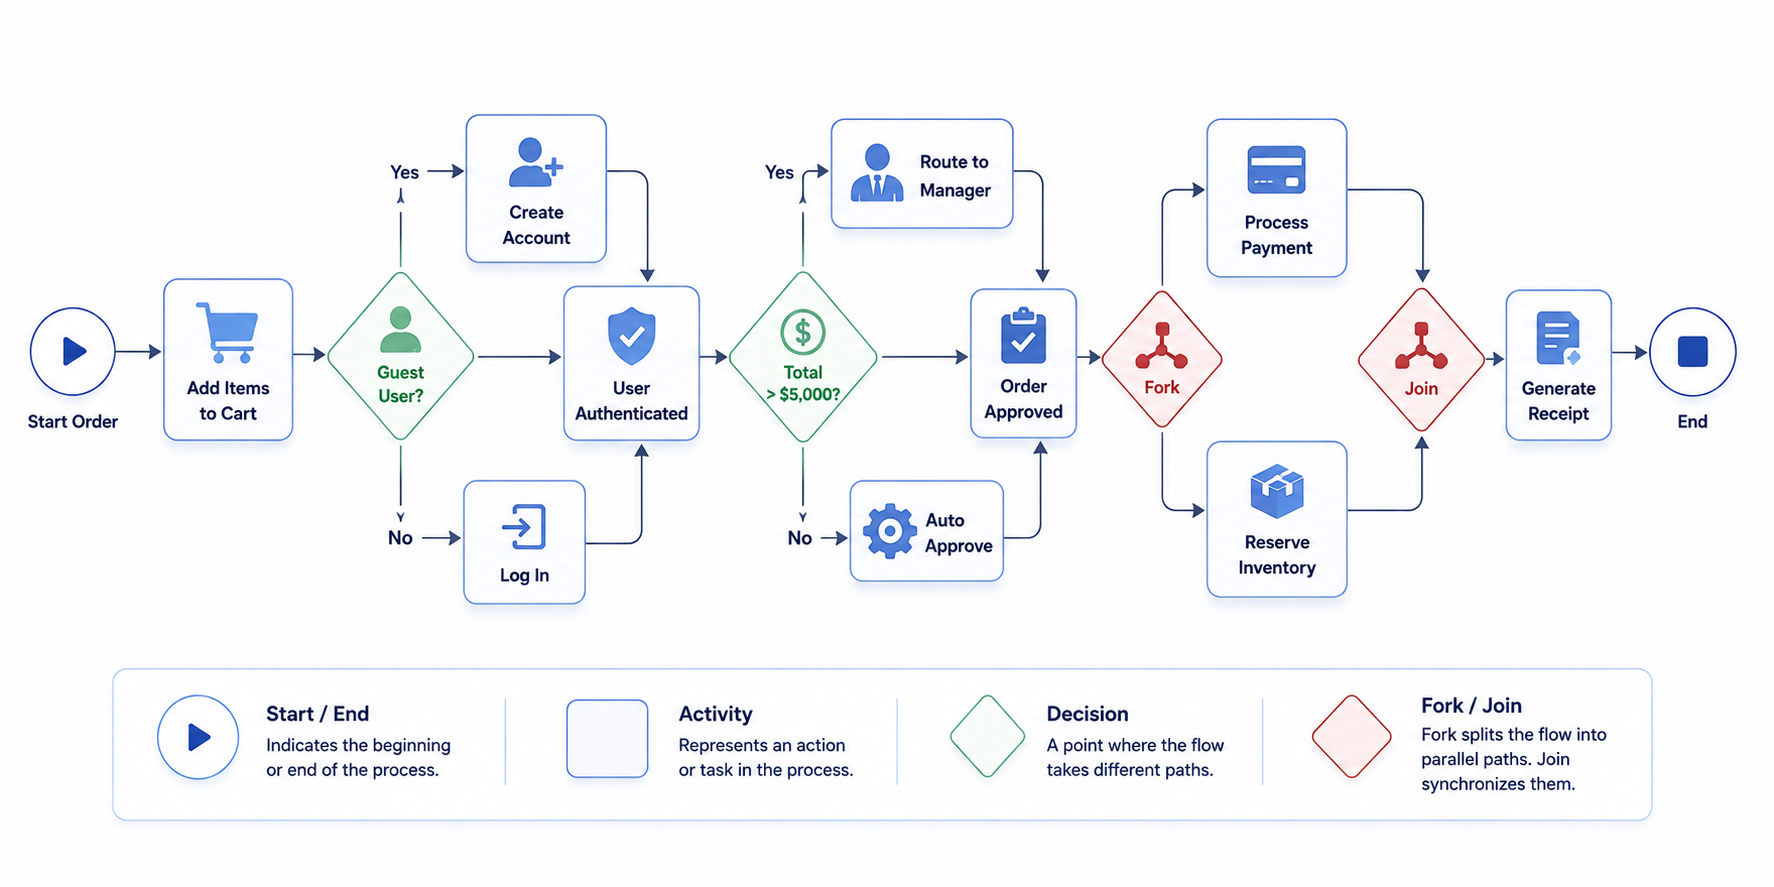
While FSMs focus on system states and transitions, activity diagrams, a subset of Unified Modeling Language (UML), and flowcharts focus on operational workflows. They model the sequential and parallel actions the system follows to accomplish a business objective.
In MBT, activity diagrams are the visual bridge between functional requirements and test paths. MBT tools analyze the diagrams and use the nodes, decision points, and parallel branches to create test paths that ensure complete test coverage.
Activity diagrams contain these core elements:
These elements represent operational steps performed by a user or the system—for example, log out, add an item, or check out.
The decision points, usually represented as diamonds, add branches to workflows using Boolean logic or conditional rules, such as “is user address specified,” “is total > $50,” and “is coupon data valid.”
These are entries that combine separate decision branches into a single workflow stream. For example, entering a coupon might create a new flow, and its approval or rejection rejoins the main checkout stream.
These elements represent parallel execution paths that branch, execute simultaneously, and rejoin each other. For example, the system might send a confirmation email while updating an inventory level.
| ID | Path | Test coverage objective |
| Path 01 | Guest -> Create Account -> Total <= $5000 (Auto Approve) -> Parallel Payment & Inventory | Positive new user flow |
| Path 02 | Existing User -> Log In -> Total > $5000 (Manager Approval) -> Parallel Payment & Inventory | High-value B2B flow |
| Path 03 | Existing User -> Log In Total > $5000 -> Manager Rejects Order | Manager rejection exception path |
| Path 04 | Existing User -> Log In -> Total <= $5000 -> Payment Processing Fails | Parallel sync failure handling |
These diagrams present a unique set of benefits, especially for complex workflows. For example:
Activity diagrams mimic a business process map, so product managers and domain experts can review and validate these models directly, without delving into the code.
MBT tools can apply graph algorithms, like cyclomatic complexity, to identify each branch and decision loop, ensuring it misses no logical paths.
These models explicitly define asynchronous, parallel workflows, making it easier to test for race conditions and synchronization logic.
With state machines tracking system status over time and activity diagrams mapping step-by-step workflows, you’d think we have testing covered.
But what happens when your system logic has complex business rules, where multiple input conditions lead to specific sets of actions? That’s where decision tables come in.
Decision tables eliminate the guesswork and drudgery when verifying compound Boolean logic. The MBT tools parse the matrix represented by decision (or truth) tables to ensure every valid combination of inputs is tested without writing redundant scripts or missing invalid sets or critical edge cases.
Decision tables comprise:
The set of variables, feature flags, or user attributes evaluated by the system. This might include the customer status, the validity of a coupon, or the total price of a shopping cart.
The explicit outcomes or behaviors triggered by a set of conditions. Valid actions could be to discount the order total, invalidate the order, or offer free shipping.
The universe of valid combinations of conditions and variables and their associated valid actions.
Decision tables eliminate the guesswork and drudgery when verifying compound Boolean logic.
Let’s say we have a promotional engine that determines discount eligibility, free shipping, and gift offers during checkout based on three criteria: customer status, promo code, and order value.
| Conditions | Rule 1 | Rule 2 | Rule 3 | Rule 4 | Rule 5 | Rule 6 | |
| 1 | Is User VIP? | Y | Y | N | N | N | N |
| 2 | Valid Promo Code? | Y | N | Y | Y | N | N |
| 3 | Order Total > $100? | Y | Y | N | Y | N | |
| 4 | Apply 20% Discount | X | |||||
| 5 | Apply 10% Discount | X | X | ||||
| 6 | Offer Free Shipping | X | X | X | X | ||
| 7 | Charge Standard Shipping | X | X |
An MBT platform might read the table above and create these tests.
| Target rule | Input conditions | Expected outputs | Test objective |
| Rule 1 | VIP User, Code = SAVE20, Order = $40 | 20% Discount Applied, Free Express Shipping | Maximum VIP Benefit Flow |
| Rule 2 | VIP User, No Code, Order = $120 | No Discount, Free Express Shipping | Threshold-based VIP Perks |
| Rule 3 | Standard User, Code = SAVE10, Order = $110 | 10% Discount Applied, Free Express Shipping | High-Value Standard User |
| Rule 4 | Standard User, Code = SAVE10, Order = $45 | 10% Discount Applied, Standard Shipping Fees | Sub-Threshold Promo Flow |
| Rule 5 | Standard User, No Code, Order = $150 | No Discount, Free Express Shipping | High-Value Base Rate Flow |
| Rule 6 | Standard User, No Code, Order = $30 | No Discount, Standard Shipping Fees | Base Minimum Order Flow |
Here are some benefits to creating a decision table:
Manual test creation often misses conflicting rule combinations. Decision tables force the explicit definition of all logical (and potentially illogical) sets of inputs before development starts.
Decision tables are useful far beyond an input for test generators. They’re a source of truth about how your application will act in production.
MBT algorithms can compress complex and extensive decision tables into the minimum number of tests required for complete coverage.
Understanding the models above and how they help build tests decoupled from specific implementations is important. But leaders evaluate testing strategies through a broader lens. How can this help them improve their team’s efficiency and lower the cost of quality?
Most teams settle on MBT because they want to break the bottlenecks created by traditional manual and code-heavy automation frameworks. So, let’s see why enterprise teams transition to a model-first strategy.
Most teams settle on MBT because they want to break the bottlenecks created by traditional manual and code-heavy automation frameworks.
Conventional test automation creates scripts that are coupled to the application’s underlying implementation, like GUI elements such as DOM locators, element IDs, or API schemas. So, UI changes or backend tweaks ripple through the test stack, breaking scripts and forcing engineers into break/code/fix cycles.
MBT breaks this cycle through abstraction. It places the API interfaces and GUI elements into a single model layer and updates it for you when you re-scan your application.
So when the code changes, teams aren’t spending hours or days refactoring linear scripts. They update the model and continue reasoning about the business logic, not test scripts.
Manual test creation relies on human intuition, which often leads to coverage gaps, especially when you’re dealing with complex business rules that mutate and change.
Decision tables and finite state machines replace guesswork with mathematical precision. MBT platforms evaluate state transition matrices and truth tables to calculate the path combinations needed to cover your application.
This helps you discover unhandled edge cases, invalid state transitions, and conflicting business logic, often before code reaches production when your move to MBT is part of a shift-left project.
Misalignments between what business analysts design, developers build, and QA tests are a perennial problem. Code-heavy test harnesses exacerbate these problems by hiding testing in a black box.
MBT relies on visual representations that serve as a common language. Business analysts review a flowchart to confirm business rules, while QA uses the same picture to drive their automated tests. This eliminates interpretation errors and ensures tests reflect business intent, not isolated technical actions.
| Dimension | Script-based automation | Model-based testing (MBT) |
| Maintenance | High; requires manual refactoring per broken script | Low; single update to central model cascades everywhere |
| Coverage quality | Limited to manually anticipated paths | Algorithmic; guarantees full state/decision coverage |
| Authoring barrier | High; requires advanced programming skills | Low; visual drag-and-drop assembly for all roles |
| Requirements alignment | Difficult; code scripts isolated from business logic | Simplified; models match business workflows |
Model-based testing has compelling advantages in scalability, maintenance, and coverage, but it’s not plug-and-play. It has several limitations, and organizations that don’t proceed with them in mind will inevitably encounter issues during its implementation.
MBT requires significant upfront effort before you can execute that first set of test scenarios.
Teams will spend considerable time mapping their business logic, designing state machines, or scanning and structuring component libraries.
MBT platforms, such as Tricentis Tosca, often need specialized configuration and integration into development workflows and CI/CD pipelines.
The initial focus in MBT is on building the models and getting the tools up and running. So, the return on investment is realized in months, not days.
MBT requires significant upfront effort before you can execute that first set of test scenarios.
MBT alters your testers’ roles, shifting their primary focus from manual execution or code-level test automation to abstraction and systems modelling.
QA engineers need to add abstract modeling to their toolboxes, such as translating user stories into state transitions, diagrams, or component models.
Engineers accustomed to writing code may resist using low-code visual models.
In MBT, your model is the single source of truth. That makes it a single source of failure, too.
If you build an activity diagram or state machine on incorrect or incomplete requirements, the MBT engine will generate incorrect or incomplete tests.
The opposite of incomplete is over-engineered. Overly dense or poorly structured models are difficult to debug and maintain.
Component-based MBT works well with standard application controls, but it can struggle with custom or highly dynamic interfaces.
Complex HTML5 canvases, shadow DOM elements, video streams, and non-standard desktop elements may require scanning custom extensions or low-level locators into a standard model.
Your model may accurately represent your application’s logical flow, but physical execution can still experience race conditions or rendering delays if you don’t properly configure runtime parameters.
| MBT advantage | Corresponding challenge | Mitigation strategy |
| Low maintenance | High initial setup cost | Start with high-value core user journeys before expanding coverage. |
| Algorithmic coverage | Risk of flawed requirements | Validate models directly with product owners and business analysts. |
| Low-code assembly | Steep modeling learning curve | Invest in formal MBT methodology training early in the transition. |
Executing MBT at scale requires a robust technology platform. Tricentis Tosca has established itself as an industry standard, translating low-code model construction into resilient automation.
Tosca operationalizes the MBT lifecycle by decoupling technical details from logical test scenarios, allowing QA teams to build, scale, and maintain large test suites with minimal friction.
The foundation of Tosca’s model-based approach is Tosca XScan, an automated scanning engine that extracts the underlying technical structure of an application. It inspects user interfaces, API endpoints, and databases to identify control properties.
Instead of hardcoding locators into test scripts, it packages them into reusable, visual modules. These modules serve as the single source of truth for the application’s interface layer, isolating technical details from business logic.
Once you’ve established your library of modules, test creation is a visual, drag-and-drop process.
Testers build end-to-end user journeys by arranging modules sequentially into test cases. Business logic remains clean and readable, reflecting actual operational requirements rather than lines of execution code.
The primary advantage of scaling MBT with Tosca lies in its efficiency. In traditional automation frameworks, an updated button ID or altered navigation flow breaks linear scripts.
With Tosca, your teams don’t alter or debug individual test cases. They rescan the updated component, save the modified module, and retest.
To see the operational and business impact of model-based test automation in the real world, consider global financial technology provider GBST.
Following a digital transformation, GBST’s development velocity sped up. But their QA process hit a major bottleneck:
GBST had attempted test automation using script-based, data-driven, and keyword-based frameworks. The resulting suites were fragile, costly to maintain, and triggered too many false positives.
Manually maintaining scripts required programming knowledge. So, regression testing became a fallback that stalled release cycles and increased their time to market.
GBST selected Tricentis Tosca for its model-based test automation approach, which removed the need to build and maintain code-based test frameworks.
Visual, low-code component models made it possible for non-technical testers to design and maintain robust test cases.
The team used Tosca to prioritize and automate their highest-risk business transactions first, integrating execution into their CI pipeline for early feedback.
Within six months, GBST automated regressions across their core products, improving speed, stability, and team collaboration. This included
You can read more about this case study here.
Model-based testing is more than just a QA framework—it’s a shift to resilient software quality with less maintenance and increased confidence.
Model-based testing is more than just a QA framework—it’s a shift to resilient software quality with less maintenance and increased confidence.
By decoupling business logic from the underlying implementation, MBT transforms testing from a potential bottleneck to an automated, trustworthy asset.
Whether through state machines, activity flows, or decision matrices, a model-first approach unifies teams behind a single source of truth that everyone can collaborate on.
Ready to see how model-first testing transforms enterprise QA? Explore how Tricentis helps teams scale model-based test automation across web, mobile, API, and enterprise applications.
This post was written by Eric Goebelbecker. Eric has worked in the financial markets in New York City for 25 years, developing infrastructure for market data and financial information exchange (FIX) protocol networks. He loves to talk about what makes teams effective (or not so effective!).
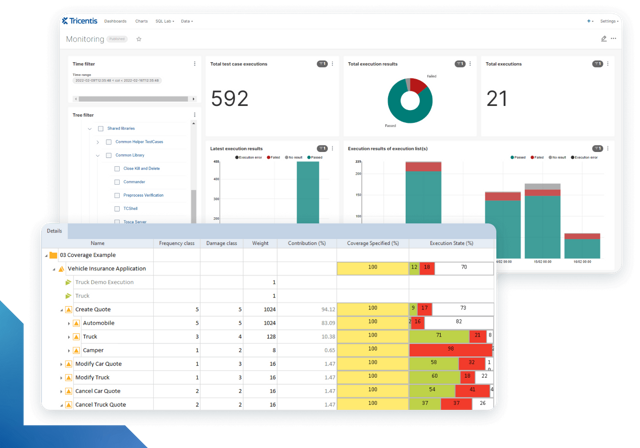
Learn more about intelligent test automation and how an AI-powered testing tool can optimize enterprise testing.
Learn more about intelligent test automation and how an AI-powered testing tool can optimize enterprise testing.

Model-based testing (MBT) is a software testing methodology that derives test cases, data, and execution paths from behavioral models rather than hand-coded scripts.
Instead of embedding artifacts like element locators directly into test code, MBT models the application’s business logic and interfaces with structures like state machines or activity flows.
This decouples test logic from the application code, allowing teams to generate and maintain test suites automatically as the system evolves.
The primary benefits of MBT are reduced test maintenance, optimized coverage, and low-code accessibility. Because it centralizes implementation details in a model layer, modifying that model automatically updates every associated test case.
Additionally, MBT engines employ graph algorithms to analyze state transitions and decision tables to achieve high path coverage and allow non-technical domain experts to assemble comprehensive tests without writing code.
Opt for model-based testing when you’re managing applications with UI or business logic updates that lead to frequent test maintenance. MBT is valuable for mixed architectures (web, API, mobile, and legacy systems) where manual regression testing creates bottlenecks.
It’s also the ideal choice when organizations want to democratize test creation, allowing business analysts and subject matter experts to design tests alongside automation engineers.