
Test management tool
A superior test management tool can help to reduce the complexity of...
What is chaos engineering? The practice of testing systems by injecting controlled failures in production. See the principles, tools, and benefits.
TL;DR
How would your software respond under unexpected and chaotic conditions? That’s where chaos engineering can help. On 19th July 2026, a single flawed CrowdStrike Falcon sensor update triggered the Blue Screen of Death (known as BSOD).
Roughly 8.5 million Windows devices took a hit—a stat estimated by Microsoft itself. The result was absolute, well, chaos.
Airlines grounded flights. Hospitals had to reschedule procedures. Manufacturing giants had to either grind to a standstill or engage manual business continuity plans. Fortune 500s cumulatively took a massive $5.4 billion hit in a single day.
The CrowdStrike team would never in their wildest dreams have imagined such a catastrophic outcome. Had they used a controlled chaos experiment to gauge the update before shipping, the defect could’ve been identified earlier, and the carnage could’ve been reduced, if not stopped altogether.
That’s the entire point of chaos engineering, really: you break things on purpose under controlled conditions so your customer isn’t the one finding out about your products’ defects.
Software is becoming easier to create using vibe coding tools like Replit, Cursor, and Loveable. But that doesn’t mean that it’s actually becoming simpler. In fact, software is becoming more distributed, more matrixed, more interdependent, and more prone to cascading failures.
This is the type of complexity that no amount of unit testing can ever hope to catch.
This post walks you through what chaos engineering actually is, how it works, the principles to keep it from becoming reckless, and some of the best practices to make it valuable for teams designing software.
Chaos engineering is the practice of experimenting on a live system to build confidence in the system’s ability to weather turbulent conditions in production.
In other words, chaos experiments are designed to put systems under enormous strain, intentionally breaking them to discover where their weaknesses are.
Armed with this knowledge, developers can fix flaws before they cause the system to break while in production, thus preventing outages and ensuring better user experiences.
You can think of chaos engineering less like being a reckless developer on a rampage and more like a fire drill. You don’t end up setting an actual fire to test an evacuation plan. But you do simulate an alarm, block out certain stairways and routes, and then time your staff to check how long it takes for them to evacuate.
Chaos engineering synonymously does the software equivalent. You sever a network connection, spike a CPU load, kill a VM mid-process (ouch!), and then watch (in anxiety) what the system does next.
Typically, chaos experiments are run in pre-production to ascertain confidence and then only graduate to production once they have been successful.
The rise of chaos engineering is attributed to Netflix’s move to an AWS cloud-based infrastructure in 2010.
To protect the experience of their customers, Netflix engineers began conducting chaos experiments to ensure they could continue to deliver quality streaming services even if experiencing downtime from Amazon servers.
Chaos engineering is designed to answer specific questions about the resiliency and functionality of systems, such as:
As a result of chaos testing, IT teams can see how systems respond to a variety of pressures in real time. It reveals bugs and weaknesses that other testing methodologies cannot.
Chaos experiments also better prepare IT teams to deal with real-world failures, reducing response times when problems occur in production environments.
At first, chaos engineering might seem a tad bit irresponsible and disruptive. But don’t worry. There indeed is a method to the madness. Let’s uncover how chaos engineering works in practice.
Naturally, each team has its own procedures and nuances, but largely the following sequence is followed:
Updated technical infrastructure diagrams and data flow diagrams can help you map out dependencies and get a good idea of the complexity involved.
Pinpoint the system you are going to target. A good way is to target one or a few interrelated components at a time. Work with the system’s owner, developer, architect, and DevOps teams to understand the system architecture.
Updated technical infrastructure diagrams and data flow diagrams can help you map out dependencies and get a good idea of the complexity involved.
Before breaking something and then comparing its effects, you need a baseline of what “normal” actually looks like.
For instance, say you’re working at a bar soap manufacturing facility, and you have an e-quality system equipped with a high-speed camera that checks if the soap labelling and packaging is up to mark or not.
You need to check how your e-quality system fares when a primary database comes crashing down. You’d measure the baseline requests per second, latency, and average quality defect detection rates.
Without such a baseline, you have no way to tell whether the chaos experiment you did was the one that caused a problem or if it was just normal system deviance.
During this phase,e it’s critical to align risk with your stakeholders. In our e-quality system example, you’d be aligning this with the manufacturing site IT/digital team, quality system owner, quality department manager, plant operations manager, and plant manager.
Depending on the scope and risk, you also might need to align regional quality and business teams. You might think that at this stage you need to inform your end users as well. After all, they should be prepared, right? Right?
Not quite. Informing your end users about a chaos experiment kind of defeats the whole purpose of the drill. You’re looking for raw, unscripted, and authentic responses from your system, as well as your end users.
Before the experiment, you need to define what you expect to happen. For instance, “If we kill this SQL DB, the backup DB should kick in immediately and continue to log all quality defects without discontinuation (business as usual).” Whether this hypothesis holds or fails is the ultimate outcome for your experiment.
Identify the right personnel required for this experiment. You will need experienced developers, architects, DevOps, SecOps, and testers who will be executing the experiment. Account for leaves and backups.
Align availability in writing since most of these roles are not full-time effort ones, and you can have competing priorities. I’ve had an instance where a whole testing regimen for Rulex workflows got delayed for weeks, just because one tester had to travel for training.
Rulex expertise is pretty rare. I learned that I had to plan well and secure backups to save hassle with resourcing during the experiment itself.
Plan this part carefully with your DevOps/SRE and business teams. Decide what you’re going to break. Here, you need to decide and align what the blast radius of your experiment should be.
Determine if it’s going to be a single instance, a specific availability zone, or a percentage of users. Document this bit carefully and rigorously.
You should also draft a system progression tree, where you start small and begin with breaking a few components within a system in pre-production environments and then progress to the system itself, and once you’re confident, you might want to scale up the experiment to a few systems. Once you’ve proven your system holds, you can follow the same pattern in production, too.
The best way to keep everyone informed is to set up a single source of truth to provide updates. If your company uses MS Teams or Slack, create a thread and post all the details there. Include hour-by-hour timelines and details of the experiment. Use this for posting periodic updates during the experiment itself.
This is where you introduce the fault to your system: killing an instance of the e-quality system, adding latency to the data relay, or removing a database altogether.
Experienced engineers will know that at this stage you should already have a kill switch in place to control the process if things go south and start to move outside safe bounds.
At this stage, you will be using the metrics you determined earlier to gauge if your hypothesis held or not. If the data is encouraging and all systems continue to operate as expected, this helps add confidence.
Congratulations! You just confirmed that your existing system is resilient enough and trustworthy. If your hypothesis fails, congratulations anyway! You just found a weakness in your system that is still cheap to fix without having to face the public brouhaha!
Once you’ve zeroed in on what needs to be fixed, you can patch it and retest. Mature teams continue to run such tests continuously and progressively, and at the same time they’re able to add a degree of automation as well.
Chaos engineering offers a number of critical benefits over other types of testing.
Chaos engineering comes into the picture to keep check on what happens when conditions stop being as expected.
Chaos testing allows IT and DevOps teams to more accurately identify and fix issues that might not be captured with other types of manual or automated software testing.
Traditional testing focuses on validating what the system is supposed to do under expected conditions. But as you well know, the world is a very uncertain place. Chaos engineering comes into the picture to keep check on what happens when conditions stop being as expected.
Take a warehousing process as an example. Say a scanner checks in inventory every time a shipment arrives. Through chaos experiments, the supply chain team might discover that their visibility dashboard goes absolutely blank the moment a single warehouse scanner loses its internet connectivity.
The logical expected output would be that only those data points that got scanned through during the internet blip get missed. This kind of defect would not show up in regular testing.
Chaos experiences are especially useful at helping IT teams understand and find weaknesses in large, complex systems such as cloud-based applications and services that must often scale rapidly.
Such systems evolve quickly, and it becomes difficult to reason through all the possible scenarios on a whiteboard alone.
Chaos experiments can expose vulnerabilities that are deeply embedded in the system’s design. IT and DevOps teams who run such experiments get a chance to upskill immensely and are able to design and build more robust systems.
Downtimes are expensive. Even a manufacturing facility producing low-cost products can incur losses on the order of hundreds and thousands of dollars per day. In fact, according to Oxford Economics, every minute of downtime costs $15,000 per minute. Do the math.
That’s roughly $900,000 per hour! That’s why service reliability is so important. Through proactive and continual chaos testing, IT teams can reduce unplanned downtime and outages to deliver a better customer experience.
By minimizing outages, chaos engineering helps to prevent revenue losses. Chaos tests also provide IT teams with the knowledge they need to design systems to scale rapidly to meet spikes in demand.
Chaos experiments help engineering leaders decide where to invest before a major scaling event. Imagine you’re an online retail platform gearing up for the next 11.11 Singles’ Day sale.
You run a chaos experiment ahead of the sale event and find that your autoscaling lags by 40 seconds under a sudden 5x traffic spike. You end up fixing this before the sale goes live. Your customer retention increases, cart abandonment decreases, and you end up 3x-ing your sales!
Start by identifying a “steady state” – a control that defines a measurable output of the system and represents typical behavior.
There are several core principles for chaos engineering that help you turn your experiments into a neat practice rather than recipes for disaster.
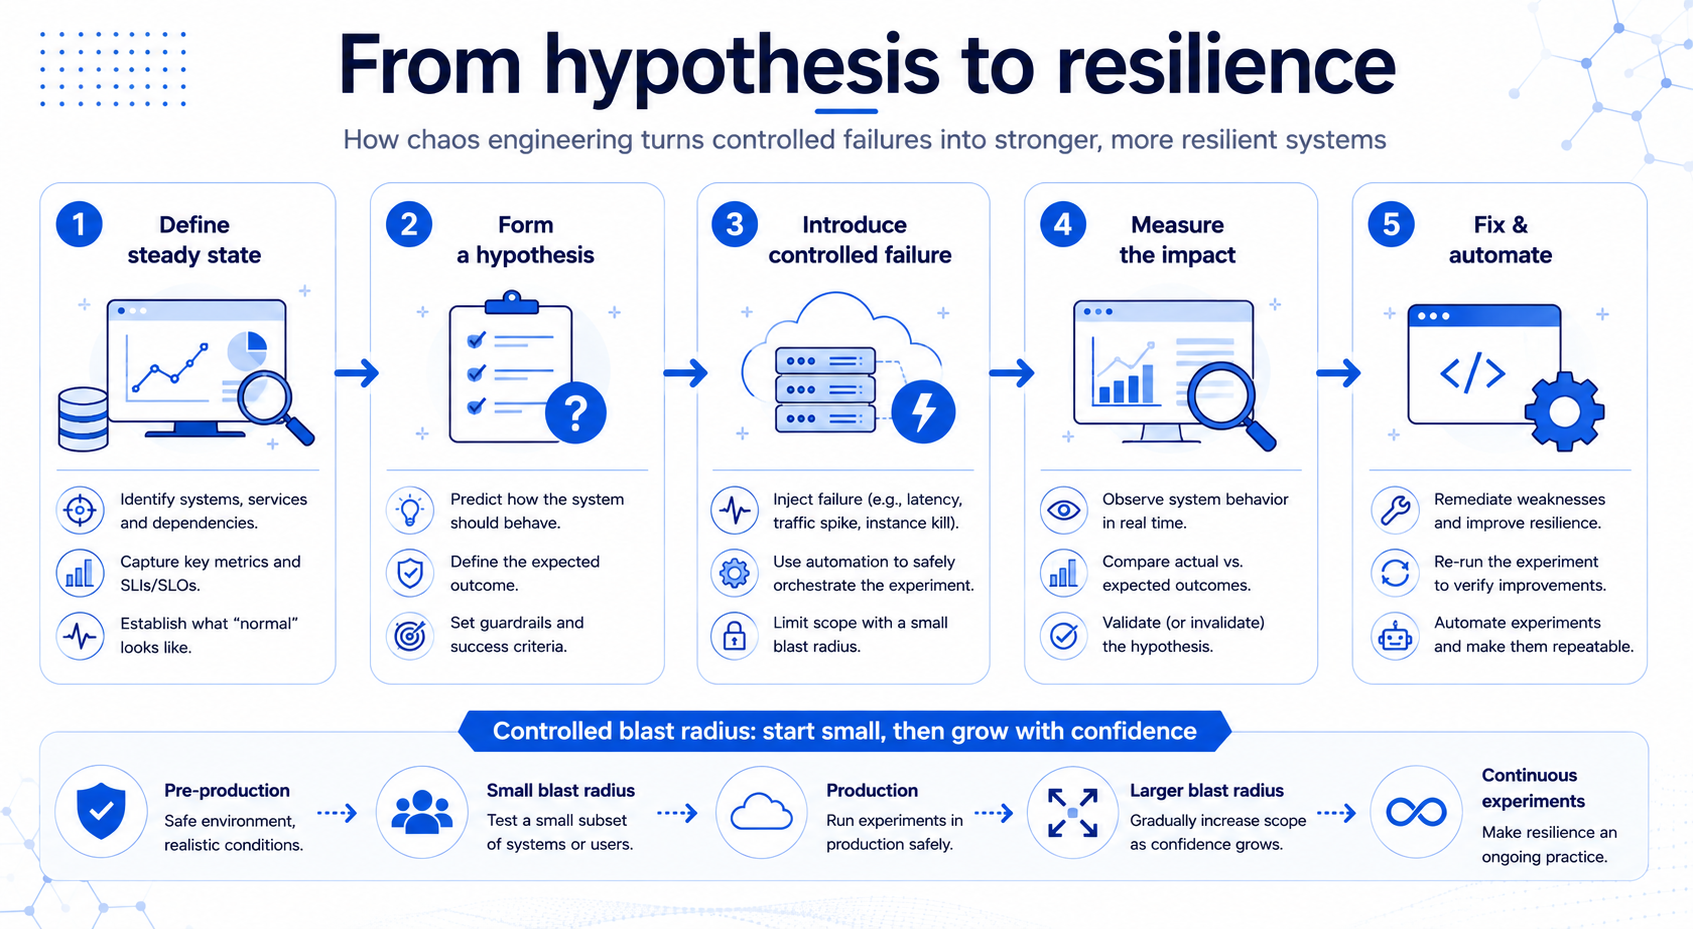
As discussed previously, start by identifying a “steady state” – a control that defines a measurable output of the system and represents typical behavior.
Using both a control group and an experiment group, introduce variables based on real-world events like malfunctioning hard drives, severed network connections, spikes in traffic, or servers that crash.
To improve results while minimizing costs, chaos engineering uses automation to continually orchestrate experiments and analyze results.
Because systems behave differently in staging vs. production environments, chaos engineering must focus on experimenting with production traffic.
Because experimenting in production can adversely impact the customer experience, initial chaos experiments should start with a small area of impact and grow as confidence in the system increases.
A common notion is that chaos engineering only happens in production environments. It doesn’t. In fact, starting out right in the middle of production is a pretty fast way to land in hot water.
A smarter idea is to start chaos engineering experiments in pre-production environments such as dev, QA, or a dedicated test environment that is representative of production. The why is simple.
Your engineers get to validate a hypothesis in a fairly low-risk setting; you can tune your blast radius, “practice,” and build confidence in the tooling and procedures, all without any of the actual customer risk.
If you’re a newbie, you wouldn’t want to burn your own money in the actual stock market, right? You’d rather play with fake money and use one of those stock market simulators to get a hang of how things flow in real life.
Production chaos engineering, on the other hand, is the real deal. This is where things get risky and where the experiment actually pays off.
The thing is, staging environments, no matter how carefully built, can’t really replicate the unpredictable traffic patterns, data volumes, and third-party dependencies/integrations of a live system.
Besides this, the sheer uncertainty is the critical ingredient here that’s supposed to expose the failures of the system.
Here is a practical path you can follow if you’re just starting out with chaos engineering:
Run the same experiment but at a reduced blast radius: a single instance, single availability zone, small percentage of non-critical users.
As we discussed above, baby steps. Run the experiment. Validate the experiment design, the monitoring, and the rollback plans. This is where you’re the safest. Feel free to engage an experienced dev who has run such experiments before.
Run the same experiment but at a reduced blast radius: a single instance, single availability zone, small percentage of non-critical users.
Expand your experiment to more instances, availability zones, traffic and services, etc. You can eventually club upstreams and downstreams together to simulate outages of interconnected systems.
Now that your confidence in your system’s robustness has cemented, start automating the experiments into your CI/CD pipelines for every release.
Skipping directly to a full-on production-level chaos experiment is straight up irresponsible. Tread with caution.
The type of chaos tests conducted on a system depends on its architecture and on the goals of the business. Some of the most common tests include:
These are typical scenarios that have at one point or the other taken down production-grade systems in real life. They serve as a good starting point to run your experiments.
It takes time and discipline to get the hang of running chaos experiments that add value. Your team shouldn’t get discouraged if the first few experiments don’t go as planned. Here is a list of best practices to help you in your journey.
To give you a better understanding, we will be taking an example of a consumer app for a hypermarket (think Tesco, Walmart). The app features product catalogs, offers,s and exclusive discounts, the usual. Let’s name our app “ShopRUs.”
Your first production experiment should be boring. Target users from a single location or even a single store. Do it with some low-key non-critical functionality at a low-traffic hour—say, after midnight. Save the more ambitious stuff for after the team has built trust in the process.
“We expect the ShopRUs app to remain up and running” doesn’t cut it. “We expect the latency for ShopRUs to remain under 300ms when our hyperscaler goes down” is more specific and more measurable.
Game days are essentially cross-functional, collaborative exercises where you work with engineering, DevOps/SRE’s, product, and sometimes biz stakeholders to simulate a major failure together in real time.
For ShopRUs, it would be a good practice to hold quarterly exercises. These exercises help spot gaps in the system. It builds the muscle memory necessary to manage actual incidents: who gets paged, who approves any rollbacks, who processes emergency changes, and most importantly, how the team reacts under pressure.
Chaos engineering is a staple for some of the largest companies in the world. Adrian Cockroft, ex VP at Amazon, in his blog post notes: “….disaster recovery testing, game days, and chaos engineering tools are all important components of a continuously resilient system.”
Baking in chaos experiments into the CI/CD pipeline helps ensure that each release gets validated.
A chaos experiment is only as good as the particular version released. Baking in chaos experiments into the CI/CD pipeline helps ensure that each release gets validated.
Too many teams start their observability tools during the experiment and then realize “Oh, we forgot to check out what our steady state was.” Without knowing your previous state, you can hardly do a good job of telling whether the experiment is working as expected or not.
Each experiment needs a kill switch. Your engineers should have rehearsed using it several times before each live experiment. Remediate any gaps observed during rehearsals and repeat till hard coded into the devs’ reflexes.
When running experiments for ShopRUs, it would be a good idea to loop in customer support, incident reporting, and/or product compliance teams. I’d even go on to loop in legal teams.
Say you run an experiment that ends up altering the listed price of products. Next thing you know, you’ve got thousands of angry customers raining down on customer support. A formal heads up in such cases is always nice.
The entire exercise and value of chaos engineering tatters if a discovered weakness becomes fuel to punish the team.
Blame only encourages people to hide problems and become diplomatic, and not in a good way. It’s extremely important to have a transparent, trust-based culture where you can have blameless postmortems without fear.
Seek mentorship from an experienced chaos engineer and preferably embed them into your team from the start of the process so they can coach your team and nudge them in the right direction.
This worthwhile investment of a few thousand dollars can save you from hundreds of thousands of dollars in potential losses on live systems.
You know what they say: “There’s no free lunch.” Chaos engineering isn’t free.
As you’ll have guessed, it isn’t risk-free, either. Most teams run into a variety of challenges:
If someone came in and suggested banging your car into a wall to check how sturdy your chassis is, understandably, this would be a hard sell. Wherever chaos engineering is a new concept, it will take time for the teams to ease in and digest the practice.
Overcoming the hesitance usually requires direct executive sponsorship. Also, it helps to start collecting a few initial wins. A track record of small, successful experiments helps boost team morale and confidence.
Poorly planned and poorly executed experiments can cause the exact outage you were meant to prevent in the first place.
Poorly planned and poorly executed experiments can cause the exact outage you were meant to prevent in the first place (can be quite ironic, not to mention awkward). That’s exactly why I’ve stressed the importance of blast radius discipline and having a kill switch when things go awry.
An experiment is as useful as the team’s ability to see what it impacted. Immature monitoring, whether through skill issues or inappropriate tool usage, means you’re flying blind. You simply wouldn’t be able to measure the metrics that matter.
Borrowing from our ShopRUs example, it could mean whether load times or accuracy of product listings on the app degraded or not.
Experienced chaos engineers are relatively a rare breed. They possess distributed systems, scripting, and monitoring expertise, all packed into one. No wonder chaos engineers make around $163,790/year, according to Glassdoor. Top earners are raking in up to $255,301!
Arguably speaking, not all systems merit chaos engineering. It makes sense where the complexity, scale, and criticality exist. The sheer time and effort required to design, plan, conduct, and analyze experiments can cause serious drain.
That’s why it’s a good idea to consult with experienced chaos engineers on whether it makes sense to run chaos experiments for your system in the first place.
Running a handful of successful experiments can very quickly give engineers the illusion that everything is hunky dory. Teams should be treating the experiment more as a snapshot (in terms of robustness) rather than a permanent guarantee for all releases to come.
Applications have become more complex and distributed. Performance testing and chaos engineering are a powerful combination to prepare complex systems for peak traffic under any condition to maximize the potential of distributed systems.
Performing load tests in dev/test environments only tests how your application will handle traffic in ideal conditions. However, things break, and dependencies fail.
Ensure your applications can perform to expectations in both ideal and degraded environments, so that even if something fails, your customers will remain unimpacted and happy with your product.
Using Neoload and Gremlin, you can easily simulate large amounts of traffic during common failure scenarios. Identify and improve parts of your system that are prone to failure or are unable to scale efficiently.
Monitor how your system degrades during failure scenarios to decide on areas for investment to improve customer uptime.
Together, Tricentis NeoLoad and Gremlin enable testing teams to answer the questions:
Launch Gremlin attacks from NeoLoad to synchronize performance tests with chaos experiments to automate and maximize the benefits of combining testing suites.
The integration between NeoLoad and Gremlin is the best automated solution for guaranteeing the performance and reliability of systems. Along with NeoLoad, Tricentis offers a suite of testing solutions and test management tools that support continuous integration throughout the software testing lifecycle.
Chaos engineering is all about finding vulnerabilities in your application, system, or workload before your customer finds it.
Each experiment starts with a fundamental question: “What happens if X breaks?” Having this answer helps you avert hundreds of thousands of dollars in lost value and lost repute for your organization.
At first, chaos engineering can feel daunting. But with the right team, tool chains, and planning, these runs can become a lifesaver for already stretched businesses.
Want to learn how Tricentis NeoLoad and Gremlin can provide load testing capabilities during your chaos engineering experiments? Download the datasheet now!
Learn more about continuous performance testing and how to deliver performance at scale.
Learn more about continuous performance testing and how to deliver performance at scale.

According to the Chaos Community, chaos engineering is “the discipline of experimenting on a system in order to build confidence in the system’s capability to withstand turbulent conditions in production.”
In other words, testers intentionally try to break a system by placing it under stress to identify weaknesses, analyze potential outages, and increase its resilience.
Failure tests are designed to break a system in a specific way to examine a single condition. These tests are typically binary and don’t reveal new understanding or knowledge about the system and its weaknesses.
In contrast, chaos tests typically produce a wealth of new information about a system and how it will behave and perform under real-world pressures and during unexpected events.
In contrast to failure tests that examine a system’s response to a single condition, chaos engineering allows organizations to test the system under unprecedented stresses and complex, diverse, real-world issues.
Chaos experiments help IT and DevOps teams understand systems better, enabling them to take steps to reduce failures and outages and improve availability and durability.
A chaos engineer designs and runs controlled experiments that intentionally disrupt your systems in production, measures the extent of the damage, analyzes how the system responds, and then finds and fixes the gaps before an actual outage catches the business off guard.
Yes. Architectures have only grown more complex. You have more distributed, microservice-based, multi-cloud, multi-language-based architectures. These systems can no longer just be reasoned about on paper. Chaos engineering exposes loopholes where teams think that none exist.
Failure mode and effects analysis (FMEA) consists of a structured and largely analytical method for anticipating how a system’s various components might fail. It gauges what the downstream effects would be.
Engineers typically chart it out on paper/whiteboard. They reason through each of the identified failure modes but do not necessarily trigger them in real life. Chaos engineering goes a step further and actually triggers those failures in real life to observe what happens.